A journal of IEEE and CAA , publishes
high-quality papers in English on original
theoretical/experimental research
and development in all areas of automation
 Volume 13
Issue 10
IEEE/CAA Journal of Automatica Sinica
| Citation: | D. Li and J. Dong, “Virtual policy iteration-based H∞ robust optimal output synchronization for unknown linear multi-agent systems,” IEEE/CAA J. Autom. Sinica, vol. 13, no. 10, pp. 2269–2279, Oct. 2026. doi: 10.1109/JAS.2026.125858

|

| [1] |
C. Chen, F. L. Lewis, K. Xie, S. Xie, and Y. Liu, “Off-policy learning for adaptive optimal output synchronization of heterogeneous multi-agent systems,” Automatica, vol. 119, Art. no. 109081, Sep. 2020.
|
| [2] |
C. Chen, F. L. Lewis, K. Xie, Y. Lyu, and S. Xie, “Distributed output data-driven optimal robust synchronization of heterogeneous multi-agent systems,” Automatica, vol. 153, Art. no. 111030, Jul. 2023.
|
| [3] |
J. Huang, Nonlinear Output Regulation: Theory and Applications. Philadelphia, USA; SIAM, 2004.
|
| [4] |
Y. Xu, Z. Yang, W. Gu, M. Li, and Z. Deng, “Robust real-time distributed optimal control based energy management in a smart grid,” IEEE Trans. Smart Grid, vol. 8, no. 4, pp. 1568−1579, Jul. 2017. doi: 10.1109/TSG.2015.2491923
|
| [5] |
K. Xiong, Q. Wei, and H. Li, “Residential energy scheduling with solar energy based on dyna adaptive dynamic programming,” IEEE/CAA J. Autom. Sinica, vol. 12, no. 2, pp. 403−413, Feb. 2025. doi: 10.1109/JAS.2024.124809
|
| [6] |
F. L. Lewis, H. Zhang, K. Hengster-Movric, and A. Das, Cooperative Control of Multi-Agent Systems: Optimal and Adaptive Design Approaches. London, UK: Springer, 2014.
|
| [7] |
W. Gao, Z.-P. Jiang, and K. Ozbay, “Data-driven adaptive optimal control of connected vehicles,” IEEE Trans. Intell. Transp. Syst., vol. 18, no. 5, pp. 1122−1133, May 2017. doi: 10.1109/TITS.2016.2597279
|
| [8] |
D. Li and J. Dong, “Approximate optimal robust tracking control based on state error and derivative without initial admissible input,” IEEE Trans. Syst. Man Cybern. Syst., vol. 54, no. 2, pp. 1059−1069, Feb. 2024. doi: 10.1109/TSMC.2023.3320653
|
| [9] |
Z. Wang, Y. Wang, and Z. Kowalczuk, “Adaptive optimal discrete-time output-feedback using an internal model principle and adaptive dynamic programming,” IEEE/CAA J. Autom. Sinica, vol. 11, no. 1, pp. 131−140, Jan. 2024. doi: 10.1109/JAS.2023.123759
|
| [10] |
F. L. Lewis, D. L. Vrabie, and V. L. Syrmos, Optimal Control. Hoboken, USA: John Wiley & Sons, 2012.
|
| [11] |
D. Wang, N. Gao, D. Liu, J. Li, and F. L. Lewis, “Recent progress in reinforcement learning and adaptive dynamic programming for advanced control applications,” IEEE/CAA J. Autom. Sinica, vol. 11, no. 1, pp. 18−36, Jan. 2024. doi: 10.1109/JAS.2023.123843
|
| [12] |
D. Liu, Q. Wei, D. Wang, X. Yang, and H. Li, “Optimal control of unknown continuous-time nonaffine nonlinear systems,” in Adaptive Dynamic Programming With Applications in Optimal Control, D. Liu, Q. Wei, D. Wang, X. Yang, and H. Li, Eds. Cham, Switzerland: Springer, 2017, pp. 309−344.
|
| [13] |
Y. Jiang and Z.-P. Jiang, “Computational adaptive optimal control for continuous-time linear systems with completely unknown dynamics,” Automatica, vol. 48, no. 10, pp. 2699−2704, Oct. 2012.
|
| [14] |
W. Gao and Z.-P. Jiang, “Adaptive dynamic programming and adaptive optimal output regulation of linear systems,” IEEE Trans. Autom. Control, vol. 61, no. 12, pp. 4164−4169, Dec. 2016. doi: 10.1109/TAC.2016.2548662
|
| [15] |
B. Luo, H.-N. Wu, and T. Huang, “Off-policy reinforcement learning for H∞ control design,” IEEE Trans. Cybern., vol. 45, no. 1, pp. 65−76, Jan. 2015. doi: 10.1109/TCYB.2014.2319577
|
| [16] |
H. Modares, F. L. Lewis, and Z.-P. Jiang, “H∞ tracking control of completely unknown continuous-time systems via off-policy reinforcement learning,” IEEE Trans. Neural Netw. Learn. Syst., vol. 26, no. 10, pp. 2550−2562, Oct. 2015. doi: 10.1109/TNNLS.2015.2441749
|
| [17] |
Y. Jiang, K. Zhang, J. Wu, C. Zhang, W. Xue, T. Chai, and F. L. Lewis, “H∞-based minimal energy adaptive control with preset convergence rate,” IEEE Trans. Cybern., vol. 52, no. 10, pp. 10078−10088, Oct. 2022.
|
| [18] |
S. Zuo, Y. Song, F. L. Lewis, and A. Davoudi, “Optimal robust output containment of unknown heterogeneous multiagent system using off-policy reinforcement learning,” IEEE Trans. Cybern., vol. 48, no. 11, pp. 3197−3207, Nov. 2018. doi: 10.1109/TCYB.2017.2761878
|
| [19] |
D. Li and J. Dong, “Cooperative optimal output tracking for discrete-time multiagent systems: Stabilizing policy iteration frameworks,” IEEE Trans. Autom. Control, vol. 71, no. 4, pp. 2746−2753, Apr. 2026.
|
| [20] |
Y. Jiang, W. Gao, J. Wu, T. Chai, and F. L. Lewis, “Reinforcement learning and cooperative H∞ output regulation of linear continuous-time multi-agent systems,” Automatica, vol. 148, Art. no. 110768, Feb. 2023.
|
| [21] |
W. Gao, Z.-P. Jiang, F. L. Lewis, and Y. Wang, “Leader-to-formation stability of multiagent systems: An adaptive optimal control approach,” IEEE Trans. Autom. Control, vol. 63, no. 10, pp. 3581−3587, Oct. 2018.
|
| [22] |
W. Gao, M. Mynuddin, D. C. Wunsch, and Z.-P. Jiang, “Reinforcement learning-based cooperative optimal output regulation via distributed adaptive internal model,” IEEE Trans. Neural Netw. Learn. Syst., vol. 33, no. 10, pp. 5229−5240, Oct. 2022. doi: 10.1109/TNNLS.2021.3069728
|
| [23] |
K. Xie, Y. Jiang, X. Yu, and W. Lan, “Data-driven cooperative optimal output regulation for linear discrete-time multi-agent systems by online distributed adaptive internal model approach,” Sci. China Inf. Sci., vol. 66, no. 7, Art. no. 170202, Jul. 2023.
|
| [24] |
T. Bian and Z.-P. Jiang, “Value iteration and adaptive dynamic programming for data-driven adaptive optimal control design,” Automatica, vol. 71, pp. 348−360, Sep. 2016. doi: 10.1016/j.automatica.2016.05.003
|
| [25] |
M. Ha, D. Wang, and D. Liu, “Discounted iterative adaptive critic designs with novel stability analysis for tracking control,” IEEE/CAA J. Autom. Sinica, vol. 9, no. 7, pp. 1262−1272, Jul. 2022. doi: 10.1109/JAS.2022.105692
|
| [26] |
B. Luo, Y. Yang, H.-N. Wu, and T. Huang, “Balancing value iteration and policy iteration for discrete-time control,” IEEE Trans. Syst. Man Cybern. Syst., vol. 50, no. 11, pp. 3948−3958, Nov. 2020. doi: 10.1109/TSMC.2019.2898389
|
| [27] |
W. Gao, C. Deng, Y. Jiang, and Z.-P. Jiang, “Resilient reinforcement learning and robust output regulation under denial-of-service attacks,” Automatica, vol. 142, Art. no. 110366, Aug. 2022.
|
| [28] |
H. Shen, C. Peng, H. Yan, and S. Xu, “Data-driven near optimization for fast sampling singularly perturbed systems,” IEEE Trans. Autom. Control, vol. 69, no. 7, pp. 4689−4694, Jul. 2024. doi: 10.1109/TAC.2024.3352703
|
| [29] |
Y. Yang, B. Kiumarsi, H. Modares, and C. Xu, “Model-free λ-policy iteration for discrete-time linear quadratic regulation,” IEEE Trans. Neural Netw. Learn. Syst., vol. 34, no. 2, pp. 635−649, Feb. 2023. doi: 10.1109/TNNLS.2021.3098985
|
| [30] |
H. Jiang and B. Zhou, “Bias-policy iteration based adaptive dynamic programming for unknown continuous-time linear systems,” Automatica, vol. 136, Art. no. 110058, Feb. 2022.
|
| [31] |
H. Shen, Y. Wang, H. Yan, and S. Xu, “Data-driven single-loop policy iteration control of uncertain singularly perturbed systems,” IEEE Trans. Autom. Control, vol. 70, no. 12, pp. 8314−8320, Dec. 2025. doi: 10.1109/TAC.2025.3581141
|
| [32] |
A. Lamperski, “Computing stabilizing linear controllers via policy iteration,” in Proc. 59th IEEE Conf. Decision and Control, Jeju South, Korea, 2020, pp. 1902−1907.
|
| [33] |
J. R. Broussard and N. Halyo, “Active flutter control using discrete optimal constrained dynamic compensators,” in Proc. American Control Conf., San Francisco, USA, 1983, pp. 1026−1034.
|
| [34] |
C. Chen, F. L. Lewis, and B. Li, “Homotopic policy iteration-based learning design for unknown linear continuous-time systems,” Automatica, vol. 138, Art. no. 110153, Apr. 2022.
|
| [35] |
W. Fan and J. Xiong, “A homotopy method for continuous-time model-free LQR control based on policy iteration,” IEEE/CAA J. Autom. Sinica, vol. 12, no. 8, pp. 1673−1682, Aug. 2025. doi: 10.1109/JAS.2025.125132
|
| [36] |
K. H. Ahmed, A. M. Massoud, S. J. Finney, and B. W. Williams, “A modified stationary reference frame-based predictive current control with zero steady-state error for LCL coupled inverter-based distributed generation systems,” IEEE Trans. Ind. Electron., vol. 58, no. 4, pp. 1359−1370, Apr. 2011. doi: 10.1109/TIE.2010.2050414
|
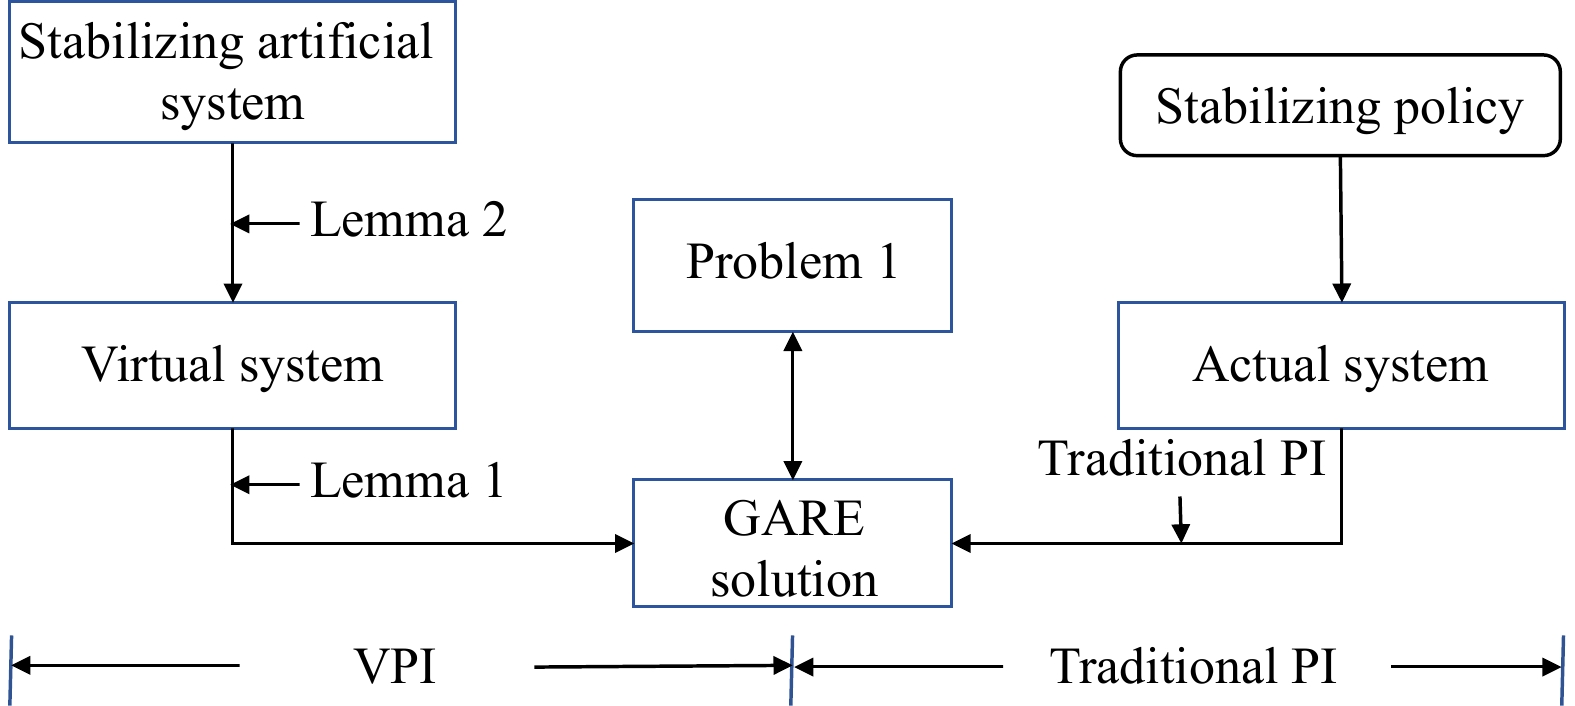
Figures(7)




 DownLoad: