A journal of IEEE and CAA , publishes
high-quality papers in English on original
theoretical/experimental research
and development in all areas of automation
IEEE/CAA Journal of Automatica Sinica
| Citation: | J. Hua, Z. Wang, X. Tian, J. Xiao, G. Wu, T. Lu, and J. Ma, IEEE/CAA J. Autom. Sinica, early access, 2026. doi: 10.1109/JAS.2026.126065

|

| [1] |
Y. Han, L. Wang, Y. Wang, and Z. Geng, “Intelligent small sample defect detection of concrete surface using novel deep learning integrating improved YOLOv5,” IEEE/CAA J. Autom. Sinica, vol. 11, no. 2, pp. 545–547, Feb. 2024. doi: 10.1109/JAS.2023.124035
|
| [2] |
H. Xu, J. Ma, Y. Yuan, H. Zhang, X. Tian, and X. Guo, “More than lightening: A self-supervised low-light image enhancement method capable for multiple degradations,” IEEE/CAA J. Autom. Sinica, vol. 11, no. 3, pp. 622–637, Mar. 2024. doi: 10.1109/JAS.2024.124263
|
| [3] |
C. Pan, J. Peng, and Z. Zhang, “Depth-guided vision transformer with normalizing flows for monocular 3D object detection,” IEEE/CAA J. Autom. Sinica, vol. 11, no. 3, pp. 673–689, Mar. 2024. doi: 10.1109/JAS.2023.123660
|
| [4] |
C. Li, C. Guo, and C. C. Loy, “Learning to enhance low-light image via zero-reference deep curve estimation,” IEEE Trans. Pattern Anal. Mach. Intell., vol. 44, no. 8, pp. 4225–4238, Aug. 2022.
|
| [5] |
Z. Cui, L. Gu, X. Sun, X. Ma, Y. Qiao, and T. Harada, “Aleth-NeRF: Illumination adaptive NeRF with concealing field assumption,” in Proc. 38th AAAI Conf. Artificial Intelligence, Vancouver, Canada, 2024, pp. 1435−1444.
|
| [6] |
K. A. Hashmi, G. Kallempudi, D. Stricker, and M. Z. Afzal, “FeatEnHancer: Enhancing hierarchical features for object detection and beyond under low-light vision,” in Proc. IEEE/CVF Int. Conf. Computer Vision, Paris, France, 2023, pp. 6702−6712.
|
| [7] |
R. Liu, L. Ma, J. Zhang, X. Fan, and Z. Luo, “Retinex-inspired unrolling with cooperative prior architecture search for low-light image enhancement,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Nashville, USA, 2021, pp. 10561−10570.
|
| [8] |
H. Zhou, W. Dong, X. Liu, S. Liu, X. Min, G. Zhai, and J. Chen, “GLARE: Low light image enhancement via generative latent feature based codebook retrieval,” in Proc. 18th European Conf. Computer Vision, Milan, Italy, 2025, pp. 36−54.
|
| [9] |
R.-Q. Wu, Z.-P. Duan, C.-L. Guo, Z. Chai, and C. Li, “RIDCP: Revitalizing real image dehazing via high-quality codebook priors,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Vancouver, Canada, 2023, pp. 22282−22291.
|
| [10] |
X. Cong, J. Gui, J. Zhang, J. Hou, and H. Shen, “A semi-supervised nighttime dehazing baseline with spatial-frequency aware and realistic brightness constraint,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Seattle, USA, 2024, pp. 2631−2640.
|
| [11] |
Y. Zhang, S. Zhou, and H. Li, “Depth information assisted collaborative mutual promotion network for single image dehazing,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Seattle, USA, 2024, pp. 2846−2855.
|
| [12] |
X. Zhu, H. Hu, S. Lin, and J. Dai, “Deformable ConvNets V2: More deformable, better results,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Long Beach, USA, 2019, pp. 9300−9308.
|
| [13] |
R. Girshick, “Fast R-CNN,” in Proc. IEEE Int. Conf. Computer Vision, Santiago, Chile, 2015, pp. 1440−1448.
|
| [14] |
S. Ren, K. He, R. Girshick, and J. Sun, “Faster R-CNN: Towards real-time object detection with region proposal networks,” IEEE Trans. Pattern Anal. Mach. Intell., vol. 39, no. 6, pp. 1137–1149, Jun. 2017. doi: 10.1109/TPAMI.2016.2577031
|
| [15] |
Z. Cai and N. Vasconcelos, “Cascade R-CNN: Delving into high quality object detection,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Salt Lake City, USA, 2018, pp. 6154−6162.
|
| [16] |
H. Zhang, H. Chang, B. Ma, N. Wang, and X. Chen, “Dynamic R-CNN: Towards high quality object detection via dynamic training,” in Proc. 16th European Conf. Computer Vision, Glasgow, UK, 2020, pp. 260−275.
|
| [17] |
T.-Y. Lin, P. Goyal, R. Girshick, K. He, and P. Dollár, “Focal loss for dense object detection,” IEEE Trans. Pattern Anal. Mach. Intell., vol. 42, no. 2, pp. 318–327, Feb. 2020. doi: 10.1109/TPAMI.2018.2858826
|
| [18] |
Z. Tian, C. Shen, H. Chen, and T. He, “FCOS: Fully convolutional one-stage object detection,” in Proc. IEEE/CVF Int. Conf. Computer Vision, Seoul, Korea (South), 2019, pp. 9626−9635.
|
| [19] |
Z. Tian, C. Shen, H. Chen, and T. He, “FCOS: A simple and strong anchor-free object detector,” IEEE Trans. Pattern Anal. Mach. Intell., vol. 44, no. 4, pp. 1922–1933, Apr. 2022. doi: 10.1109/tpami.2020.3032166
|
| [20] |
T. Kong, F. Sun, H. Liu, Y. Jiang, L. Li, and J. Shi, “FoveaBox: Beyound anchor-based object detection,” IEEE Trans. Image Process., vol. 29, pp. 7389–7398, Jun. 2020. doi: 10.1109/TIP.2020.3002345
|
| [21] |
S. Zhang, C. Chi, Y. Yao, Z. Lei, and S. Z. Li, “Bridging the gap between anchor-based and anchor-free detection via adaptive training sample selection,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Seattle, USA, 2020, pp. 9759−9768.
|
| [22] |
X. Dai, Y. Chen, B. Xiao, D. Chen, M. Liu, L. Yuan, and L. Zhang, “Dynamic head: Unifying object detection heads with attentions,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Nashville, USA, 2021, pp. 7373−7382.
|
| [23] |
J. Redmon, S. Divvala, R. Girshick, and A. Farhadi, “You only look once: Unified, real-time object detection,” in Proc. IEEE Conf. Computer Vision and Pattern Recognition, Las Vegas, USA, 2016, pp. 779−788.
|
| [24] |
J. Redmon and A. Farhadi, “YOLO9000: Better, faster, stronger,” in Proc. IEEE Conf. Computer Vision and Pattern Recognition, Honolulu, USA, 2017, pp. 6517−6525.
|
| [25] |
R. Joseph and F. Ali, “YOLOv3: An incremental improvement,” arXiv preprint arXiv: 1804.02767, 2018.
|
| [26] |
A. Bochkovskiy, C.-Y. Wang, and H.-Y. M. Liao, “YOLOv4: Optimal speed and accuracy of object detection,” arXiv preprint arXiv: 2004.10934, 2020.
|
| [27] |
C. Li, L. Li, H. Jiang, K. Weng, Y. Geng, L. Li, et al., “YOLOv6: A single-stage object detection framework for industrial applications,” arXiv preprint arXiv: 2209.02976, 2022.
|
| [28] |
C.-Y. Wang, A. Bochkovskiy, and H.-Y. M. Liao, “YOLOv7: Trainable bag-of-freebies sets new state-of-the-art for real-time object detectors,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Vancouver, Canada, 2023, pp. 7464−7475.
|
| [29] |
Z. Ge, S. Liu, F. Wang, Z. Li, and J. Sun, “YOLOX: Exceeding YOLO series in 2021,” arXiv preprint arXiv: 2107.08430, 2021.
|
| [30] |
Z.-X. Li, Y.-L. Wang, and F. Wang, “DI-YOLOv5: An improved dual-wavelet-based YOLOv5 for dense small object detection,” IEEE/CAA J. Autom. Sinica, vol. 12, no. 2, pp. 457–459, Feb. 2025. doi: 10.1109/JAS.2024.124368
|
| [31] |
H. Sun, Y. Wang, J. Du, and R. Wang, “MFE-YOLO: A multi-feature fusion algorithm for airport bird detection,” ICCK Trans. Intell. Syst., vol. 2, no. 2, pp. 85–94, May 2025. doi: 10.62762/TIS.2025.323887
|
| [32] |
N. Carion, F. Massa, G. Synnaeve, N. Usunier, A. Kirillov, and S. Zagoruyko, “End-to-end object detection with transformers,” in Proc. 16th European Conf. Computer Vision, Glasgow, UK, 2020, pp. 213−229.
|
| [33] |
X. Zhu, W. Su, L. Lu, B. Li, X. Wang, and J. Dai, “Deformable DETR: Deformable transformers for end-to-end object detection,” in Proc. 9th Int. Conf. Learning Representations, Austria, 2021. [Online]. Available: https://iclr.cc/Conferences/2021
|
| [34] |
S. Liu, F. Li, H. Zhang, X. Yang, X. Qi, H. Su, J. Zhu, and L. Zhang, “DAB-DETR: Dynamic anchor boxes are better queries for DETR,” in Proc. 10th Int. Conf. Learning Representations, 2022. [Online]. Available: https://iclr.cc/Conferences/2022
|
| [35] |
F. Li, H. Zhang, S. Liu, J. Guo, L. M. Ni, and L. Zhang, “DN-DETR: Accelerate DETR training by introducing query DeNoising,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, New Orleans, USA, 2022, pp. 13609−13617.
|
| [36] |
F. Li, A. Zeng, S. Liu, H. Zhang, H. Li, L. Zhang, and L. M. Ni, “Lite DETR: An interleaved multi-scale encoder for efficient DETR,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Vancouver, Canada, 2023, pp. 18558−18567.
|
| [37] |
H. Zhang, F. Li, S. Liu, L. Zhang, H. Su, J. Zhu, L. M. Ni, and H.-Y. Shum, “DINO: DETR with improved DeNoising anchor boxes for end-to-end object detection,” in Proc. 11th Int. Conf. Learning Representations, Kigali, Rwanda, 2023.
|
| [38] |
Z. Zong, G. Song, and Y. Liu, “DETRs with collaborative hybrid assignments training,” in Proc. IEEE/CVF Int. Conf. Computer Vision, Paris, France, 2023, pp. 6725−6735.
|
| [39] |
X. Hou, M. Liu, S. Zhang, P. Wei, and B. Chen, “Salience DETR: Enhancing detection transformer with hierarchical salience filtering refinement,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Seattle, USA, 2024, pp. 17574−17583.
|
| [40] |
X. Hou, M. Liu, S. Zhang, P. Wei, B. Chen, and X. Lan, “Relation DETR: Exploring explicit position relation prior for object detection,” in Proc. 18th European Conf. Computer Vision, Milan, Italy, 2025, pp. 89−105.
|
| [41] |
Y. Zhang, J. Zhang, and X. Guo, “Kindling the darkness: A practical low-light image enhancer,” in Proc. 27th ACM Int. Conf. Multimedia, Nice, France, 2019, pp. 1632−1640.
|
| [42] |
C. Guo, C. Li, J. Guo, C. C. Loy, J. Hou, S. Kwong, and R. Cong, “Zero-reference deep curve estimation for low-light image enhancement,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Seattle, USA, 2020, pp. 1777−1786.
|
| [43] |
Y. Jiang, X. Gong, D. Liu, Y. Cheng, C. Fang, X. Shen, J. Yang, P. Zhou, and Z. Wang, “EnlightenGAN: Deep light enhancement without paired supervision,” IEEE Trans. Image Process., vol. 30, pp. 2340–2349, Jan. 2021. doi: 10.1109/TIP.2021.3051462
|
| [44] |
F. Lv, Y. Li, and F. Lu, “Attention guided low-light image enhancement with a large scale low-light simulation dataset,” Int. J. Comput. Vis., vol. 129, no. 7, pp. 2175–2193, Jul. 2021. doi: 10.1007/s11263-021-01466-8
|
| [45] |
W. Liu, G. Ren, R. Yu, S. Guo, J. Zhu, and L. Zhang, “Image-adaptive YOLO for object detection in adverse weather conditions,” in Proc. 36th AAAI Conf. Artificial Intelligence, 2022, pp. 1792−1800. [Online]. Available: https://aaai-2022.virtualchair.net/venue
|
| [46] |
Z. Cui, G.-J. Qi, L. Gu, S. You, Z. Zhang, and T. Harada, “Multitask AET with orthogonal tangent regularity for dark object detection,” in Proc. IEEE/CVF Int. Conf. Computer Vision, Montreal, Canada, 2021, pp. 2533−2542.
|
| [47] |
J. Wang, Y. He, K. Li, S. Li, L. Zhao, J. Yin, M. Zhang, T. Shi, and X. Wang, “MDANet: A multi-stage domain adaptation framework for generalizable low-light image enhancement,” Neurocomputing, vol. 627, Art. no. 129572, Apr. 2025. doi: 10.1016/j.neucom.2025.129572
|
| [48] |
H. Dong, J. Pan, L. Xiang, Z. Hu, X. Zhang, F. Wang, and M.-H. Yang, “Multi-scale boosted dehazing network with dense feature fusion,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Seattle, USA, 2020, pp. 2154−2164.
|
| [49] |
C. Guo, Q. Yan, S. Anwar, R. Cong, W. Ren, and C. Li, “Image dehazing transformer with transmission-aware 3D position embedding,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, New Orleans, USA, 2022, pp. 5802−5810.
|
| [50] |
Y. Shao, L. Li, W. Ren, C. Gao, and N. Sang, “Domain adaptation for image dehazing,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Seattle, USA, 2020, pp. 2805−2814.
|
| [51] |
Z. Chen, Y. Wang, Y. Yang, and D. Liu, “PSD: Principled synthetic-to-real dehazing guided by physical priors,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Nashville, USA, 2021, pp. 7180−7189.
|
| [52] |
Y. Yang, C. Wang, R. Liu, L. Zhang, X. Guo, and D. Tao, “Self-augmented unpaired image dehazing via density and depth decomposition,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, New Orleans, SUA, 2022, pp. 2027−2036.
|
| [53] |
T.-Y. Lin, P. Dollár, R. Girshick, K. He, B. Hariharan, and S. Belongie, “Feature pyramid networks for object detection,” in Proc. IEEE Conf. Computer Vision and Pattern Recognition, Honolulu, USA, 2017, pp. 936−944.
|
| [54] |
S. Liu, L. Qi, H. Qin, J. Shi, and J. Jia, “Path aggregation network for instance segmentation,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Salt Lake City, USA, 2018, pp. 8759−8768.
|
| [55] |
Q. Zhao, T. Sheng, Y. Wang, Z. Tang, Y. Chen, L. Cai, and H. Ling, “M2Det: A single-shot object detector based on multi-level feature pyramid network,” in Proc. 33rd AAAI Conf. Artificial Intelligence, Honolulu, USA, 2019, pp. 9259−9266.
|
| [56] |
F. Wang and S. Yi, “Spatio-temporal feature soft correlation concatenation aggregation structure for video action recognition networks,” ICCK Trans. Sens. Commun. Control, vol. 1, no. 1, pp. 60–71, Oct. 2024. doi: 10.62762/TSCC.2024.212751
|
| [57] |
S. Rafique, S. Iqbal, D. Ali, and F. Khan, “Navigating ethical challenges in 6G-enabled smart cities: Privacy, equity, and governance,” ICCK Trans. Sens. Commun. Control, vol. 2, no. 1, pp. 48–65, Mar. 2025. doi: 10.62762/TSCC.2025.291581
|
| [58] |
E. Mohammed, A. Khan, W. Ullah, W. Khan, and M. J. Ahmed, “Efficient polyp segmentation via attention-guided lightweight network with progressive multi-scale fusion,” ICCK Trans. Intell. Syst., vol. 2, no. 2, pp. 95–108, Jun. 2025. doi: 10.62762/TIS.2025.389995
|
| [59] |
J. Hua, Z. Wang, J. Chang, H. Zou, G. Wu, and J. Ma, “MSTDNet: Multi-scale traffic object detection network with smooth information perception,” Pattern Recognit., vol. 172, Art. no. 112579, Apr. 2026. doi: 10.1016/j.patcog.2025.112579
|
| [60] |
Q. Chen, Y. Wang, T. Yang, X. Zhang, J. Cheng, and J. Sun, “You only look one-level feature,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Nashville, USA, 2021, pp. 13039−13048.
|
| [61] |
G. Yang, J. Lei, Z. Zhu, S. Cheng, Z. Feng, and R. Liang, “AFPN: Asymptotic feature pyramid network for object detection,” in Proc. IEEE Int. Conf. Systems, Man, and Cybernetics, Honolulu, USA, 2023, pp. 2184−2189.
|
| [62] |
L. Zhu, Z. Deng, X. Hu, C.-W. Fu, X. Xu, J. Qin, and P.-A. Heng, “Bidirectional feature pyramid network with recurrent attention residual modules for shadow detection,” in Proc. 15th European Conf. Computer Vision, Munich, Germany, 2018, pp. 122−137.
|
| [63] |
P.-Y. Chen, M.-C. Chang, J.-W. Hsieh, and Y.-S. Chen, “Parallel residual bi-fusion feature pyramid network for accurate single-shot object detection,” IEEE Trans. Image Process., vol. 30, pp. 9099–9111, Nov. 2021. doi: 10.1109/TIP.2021.3118953
|
| [64] |
C. Wang, W. He, Y. Nie, J. Guo, C. Liu, K. Han, and Y. Wang, “Gold-YOLO: Efficient object detector via gather-and-distribute mechanism,” in Proc. 37th Int. Conf. Neural Information Processing Systems, New Orleans, USA, 2023, Art. no. 2224.
|
| [65] |
X. Ding, X. Zhang, J. Han, and G. Ding, “Scaling up your kernels to 31×31: Revisiting large kernel design in CNNs,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, New Orleans, USA, 2022, pp. 11953−11965.
|
| [66] |
S. Lin, F. Tang, W. Dong, X. Pan, and C. Xu, “SMNet: Synchronous multi-scale low light enhancement network with local and global concern,” IEEE Trans. Multimedia, vol. 25, pp. 9506–9517, Mar. 2023. doi: 10.1109/TMM.2023.3254141
|
| [67] |
Y. Qi, Y. He, X. Qi, Y. Zhang, and G. Yang, “Dynamic snake convolution based on topological geometric constraints for tubular structure segmentation,” in Proc. IEEE/CVF Int. Conf. Computer Vision, Paris, France, 2023, pp. 6047−6056.
|
| [68] |
Y. P. Loh and C. S. Chan, “Getting to know low-light images with the exclusively dark dataset,” Comput. Vis. Image Underst., vol. 178, pp. 30–42, Jan. 2019. doi: 10.1016/j.cviu.2018.10.010
|
| [69] |
W. Yang, Y. Yuan, W. Ren, J. Liu, W. J. Scheirer, Z. Wang, et al, “Advancing image understanding in poor visibility environments: A collective benchmark study,” IEEE Trans. Image Process., vol. 29, pp. 5737–5752, Mar. 2020. doi: 10.1109/TIP.2020.2981922
|
| [70] |
C. Sakaridis, D. Dai, S. Hecker, and L. Van Gool, “Model adaptation with synthetic and real data for semantic dense foggy scene understanding,” in Proc. 15th European Conf. Computer Vision, Munich, Germany, 2018, pp. 707−724.
|
| [71] |
C. Feng, Z. Chen, X. Li, C. Wang, J. Yang, M.-M. Cheng, Y. Dai, and Q. Fu, “HazyDet: Open-source benchmark for drone-view object detection with depth-cues in hazy scenes,” arXiv preprint arXiv: 2409.19833, 2025.
|
| [72] |
T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan, P. Dollár, and C. L. Zitnick, “Microsoft COCO: Common objects in context,” in Proc. 13th European Conf. Computer Vision, Zurich, Switzerland, 2014, pp. 740−755.
|
| [73] |
N. Wang, Y. Gao, H. Chen, P. Wang, Z. Tian, C. Shen, and Y. Zhang, “NAS-FCOS: Fast neural architecture search for object detection,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Seattle, USA, 2020, pp. 11940−11948.
|
| [74] |
H. Zhang, Y. Wang, F. Dayoub, and N. Sünderhauf, “VarifocalNet: An IoU-aware dense object detector,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Nashville, USA, 2021, pp. 8514−8523.
|
| [75] |
D. Meng, X. Chen, Z. Fan, G. Zeng, H. Li, Y. Yuan, L. Sun, and J. Wang, “Conditional DETR for fast training convergence,” in Proc. IEEE/CVF Int. Conf. Computer Vision, Montreal, Canada, 2021, pp. 3631−3640.
|
| [76] |
X. Li, C. Lv, W. Wang, G. Li, L. Yang, and J. Yang, “Generalized focal loss: Towards efficient representation learning for dense object detection,” IEEE Trans. Pattern Anal. Mach. Intell., vol. 45, no. 3, pp. 3139–3153, Mar. 2023. doi: 10.1109/tpami.2022.3180392
|
| [77] |
P. Sun, R. Zhang, Y. Jiang, T. Kong, C. Xu, W. Zhan, M. Tomizuka, Z. Yuan, and P. Luo, “Sparse R-CNN: An end-to-end framework for object detection,” IEEE Trans. Pattern Anal. Mach. Intell., vol. 45, no. 12, pp. 15650–15664, Dec. 2023. doi: 10.1109/TPAMI.2023.3292030
|
| [78] |
S. Zhang, X. Wang, J. Wang, J. Pang, C. Lyu, W. Zhang, P. Luo, and K. Chen, “Dense distinct query for end-to-end object detection,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Vancouver, Canada, 2023, pp. 7329−7338.
|
| [79] |
X. Liu, Y. Ma, Z. Shi, and J. Chen, “GridDehazeNet: Attention-based multi-scale network for image dehazing,” in Proc. IEEE/CVF Int. Conf. Computer Vision, Seoul, Korea (South), 2019, pp. 7314−7323.
|
| [80] |
L. Lu, Q. Xiong, B. Xu, and D. Chu, “MixDehazeNet: Mix structure block for image dehazing network,” in Proc. Int. Joint Conf. Neural Networks, Yokohama, Japan, 2024, pp. 1−10.
|
| [81] |
Y. Cui and A. Knoll, “Dual-domain strip attention for image restoration,” Neural Networks, vol. 171, pp. 429–439, Mar. 2024. doi: 10.1016/j.neunet.2023.12.003
|
| [82] |
X. Qin, Z. Wang, Y. Bai, X. Xie, and H. Jia, “FFA-Net: Feature fusion attention network for single image dehazing,” in Proc. 34th AAAI Conf. Artificial Intelligence, New York, USA, 2020, pp. 11908−11915.
|
| [83] |
Y. Song, Z. He, H. Qian, and X. Du, “Vision transformers for single image dehazing,” IEEE Trans. Image Process., vol. 32, pp. 1927–1941, Mar. 2023. doi: 10.1109/TIP.2023.3256763
|
| [84] |
Y. Song, Y. Zhou, H. Qian, and X. Du, “Rethinking performance gains in image dehazing networks,” arXiv preprint arXiv: 2209.11448, 2022.
|
| [85] |
Y. Zheng, J. Zhan, S. He, J. Dong, and Y. Du, “Curricular contrastive regularization for physics-aware single image dehazing,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Vancouver, Canada, 2023, pp. 5785−5794.
|
| [86] |
K. He, J. Sun, and X. Tang, “Single image haze removal using dark channel prior,” IEEE Trans. Pattern Anal. Mach. Intell., vol. 33, no. 12, pp. 2341–2353, Dec. 2011. doi: 10.1109/TPAMI.2010.168
|
| [87] |
C. Guo, B. Fan, Q. Zhang, S. Xiang, and C. Pan, “AugFPN: Improving multi-scale feature learning for object detection,” in Proc. IEEE/CVF Conf. Computer Vision and Pattern Recognition, Seattle, USA, 2020, pp. 12592−12601.
|
| [88] |
D. Zhang, H. Zhang, J. Tang, M. Wang, X. Hua, and Q. Sun, “Feature pyramid transformer,” in Proc. 16th European Conf. Computer Vision, Glasgow, UK, 2020, pp. 323−339.
|
| [89] |
J. Ma and B. Chen, “Dual refinement feature pyramid networks for object detection,” arXiv preprint arXiv: 2012.01733, 2020.
|
| [90] |
G. Zhao, W. Ge, and Y. Yu, “GraphFPN: Graph feature pyramid network for object detection,” in Proc. IEEE/CVF Int. Conf. Computer Vision, Montreal, Canada, 2021, pp. 2743−2752.
|
| [91] |
J. Xie, Y. Pang, J. Nie, J. Cao, and J. Han, “Latent feature pyramid network for object detection,” IEEE Trans. Multimedia, vol. 25, pp. 2153–2163, Jan. 2023. doi: 10.1109/TMM.2022.3143707
|
| [92] |
L. Zhu, F. Lee, J. Cai, H. Yu, and Q. Chen, “An improved feature pyramid network for object detection,” Neurocomputing, vol. 483, pp. 127–139, Apr. 2022. doi: 10.1016/j.neucom.2022.02.016
|
| [93] |
K. He, G. Gkioxari, P. Dollár, and R. Girshick, “Mask R-CNN,” in Proc. IEEE Int. Conf. Computer Vision, Venice, Italy, 2017, pp. 2980−2988.
|
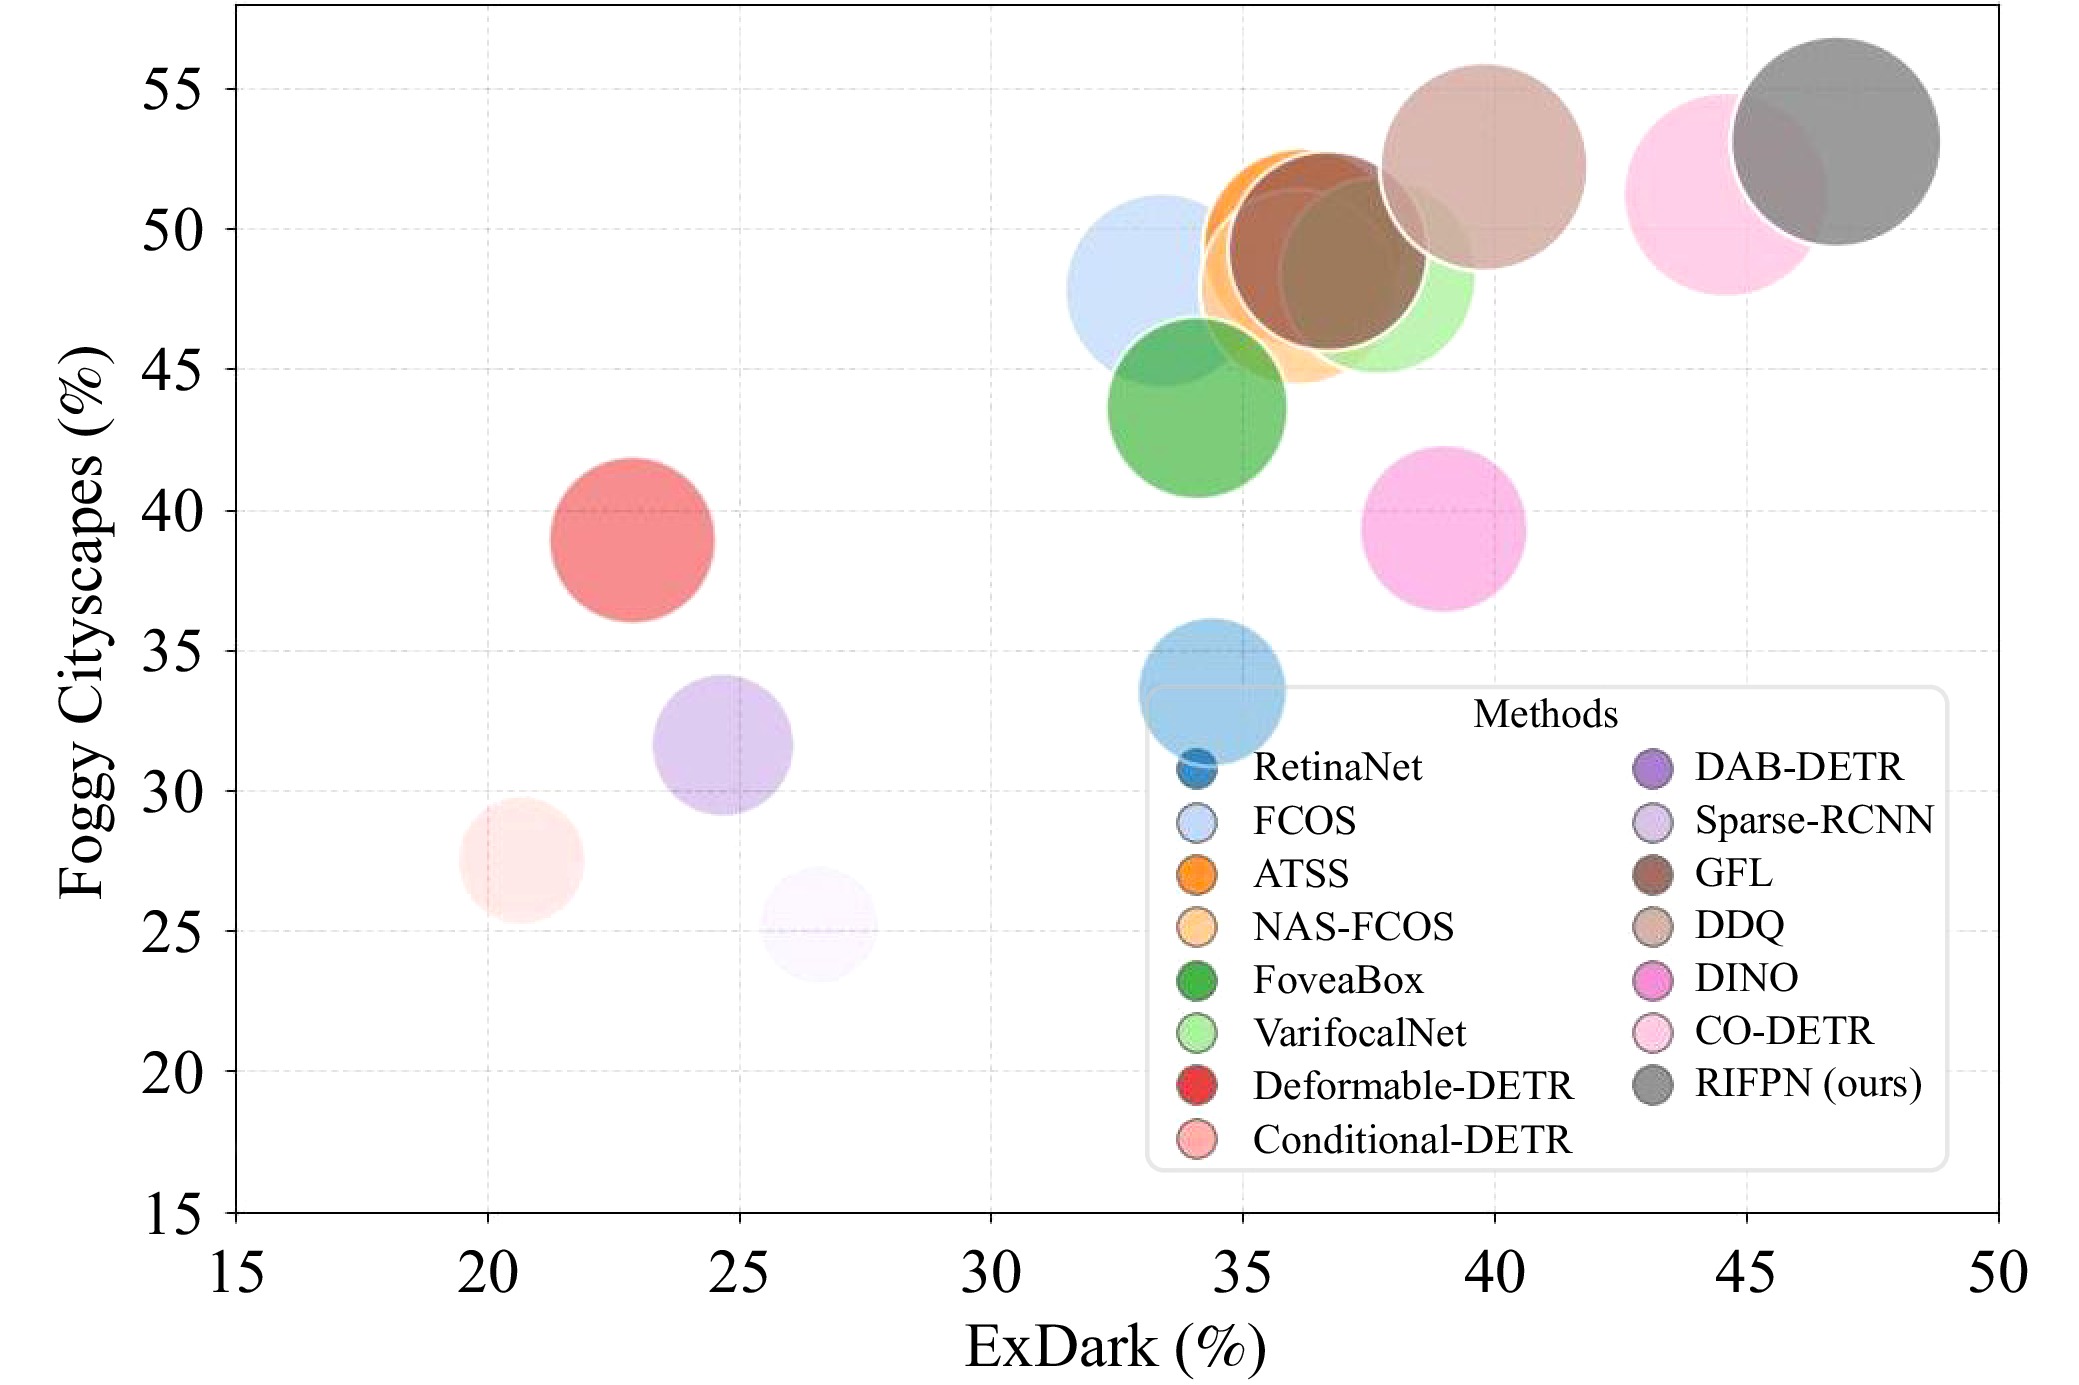
Figures(15) / Tables(15)




 DownLoad: